The site worked yesterday. Today the browser shows an error. This is where the most dangerous instinct appears: immediately change something — restart the server, reissue the certificate, edit DNS or rewrite the Nginx configuration.
Sometimes the site comes back after that. But an unpleasant question remains: what exactly was broken? Good diagnostics work differently. A website is a chain of several systems. Check them in order and the search area narrows very quickly.
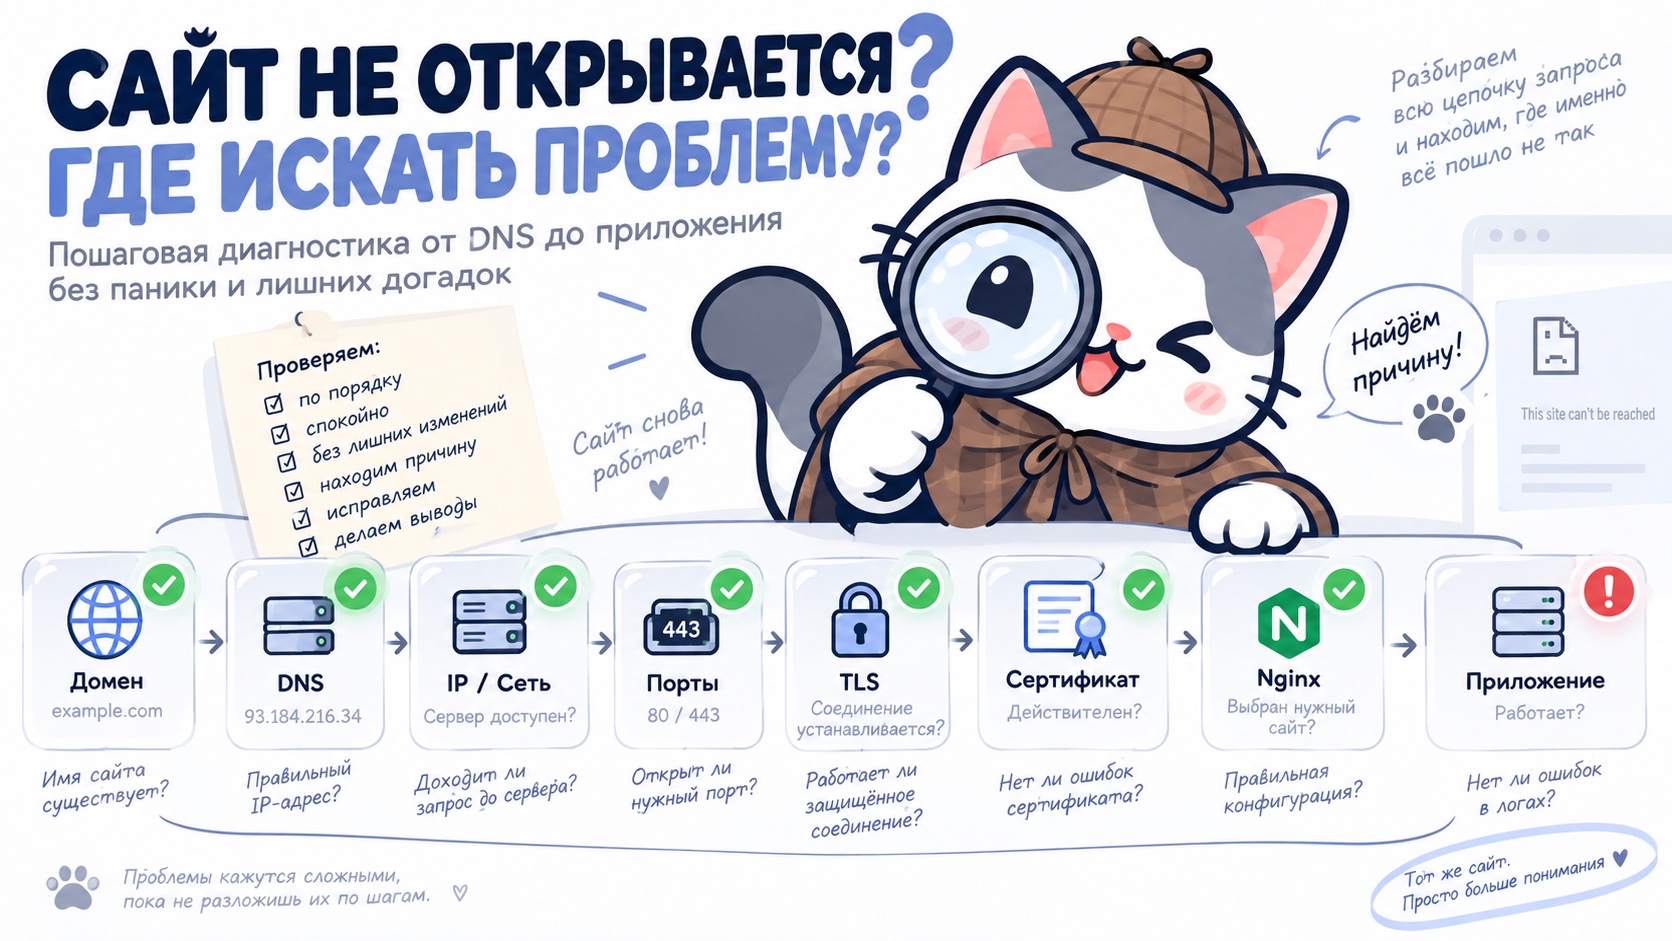
First, remember the whole request path
When someone opens https://example.com, the sequence is roughly:
Every element depends on the previous one. If DNS sends the browser to the wrong server, studying Nginx on the correct machine is pointless. If TLS is already connecting, there is no reason to change DNS again because of an application error.
Step one: does the domain exist at all?
Start with the obvious thing people sometimes forget. Is the domain spelled correctly? Has its registration expired? Is the intended domain zone being used? Is there a typo such as exmaple.com instead of example.com?
Until the name is correct, the rest of the chain does not matter.
Step two: what does DNS say?
The next question is: which IP does the domain point to right now?
example.com → 203.0.113.10Compare that address with the IP of the server that actually hosts the site. If the values differ, the problem is already found: the request is arriving at the wrong machine.
If DNS shows the old IP
This does not necessarily mean the new record failed to save. A cache may be involved. The old answer can remain for a while at the ISP, operating system, router or local DNS resolver.
If the authoritative DNS already returns the new address but a particular device still gets the old one, the usual fix is not to change the record again but to wait for the TTL to expire.
If DNS is correct, move on
Suppose example.com → 203.0.113.10, and that really is the IP of the intended server. The first layer can be considered checked.
We have already eliminated a huge class of possible causes.
Is the server reachable at all?
Now determine whether there is a network path to the machine. The server may be powered off, the virtual machine stopped, the route unavailable, a firewall blocking the connection, or the hosting provider experiencing an outage.
DNS can be completely correct in all of these cases. It knows where to go, but it cannot guarantee that anyone is home.
A port is a separate check
Even if the server is reachable over the network, the required service may not be accepting connections. For a website, two ports matter most: 80 for HTTP and 443 for HTTPS.
HTTP works, HTTPS does not
This is one of the most useful diagnostic states. If http://example.com opens but https://example.com does not, the base server is reachable and DNS works. The problem is somewhere around port 443, TLS or the HTTPS configuration.
HTTPS opens, but the browser complains about the certificate
This means the browser has already found the IP, connected to the server, reached port 443, started a TLS connection and received a certificate.
Now inspect the certificate itself: does it match the domain, has it expired, is the chain of trust intact, and did Nginx perhaps select the HTTPS block for another site?
A certificate for another site is an especially useful signal
If you open example.com and the browser presents a certificate for another-site.com, the request probably reached the server but Nginx selected the wrong virtual host.
Check server_name, the HTTPS server block, SNI and the default configuration.
The standard Nginx page opens
That is actually good news. DNS probably brought the request to the server, the port is reachable, Nginx is running and the browser received an HTTP response.
The question is now much narrower: why did Nginx choose the wrong site? Common causes are an incorrect server_name, an inactive configuration, or default_server.
Check server_name
server {
    listen 443 ssl;
    server_name example.com www.example.com;
}
If the name does not match, Nginx will not guess and may choose another block.
The configuration exists, but Nginx is not reading it
A file can sit on the server, look perfect and still have no effect at all. For example, it may be in /etc/nginx/sites-available/ but not connected through /etc/nginx/sites-enabled/.
At that point, the issue is no longer the contents of the file: Nginx simply is not using it.
That is why nginx -t comes first
After changing the configuration, it is useful to follow the same sequence every time.
nginx -t
systemctl reload nginx
If Nginx chose the correct site
Suppose DNS is correct, HTTPS works, the certificate is valid and Nginx selects the intended server_name. Now find out what Nginx is supposed to return: files from disk or an internal application.
Static site: check root
root /var/www/example;
index index.html;
Now make sure the file really exists at /var/www/example/index.html. A typical mistake is that the files are in one directory while Nginx is looking in another.
404 is already a response
404 Not Found is often treated as a total site failure, even though from a diagnostic point of view it is a fairly successful result. The server received the request, Nginx processed it and produced a response.
The problem is now at the route or missing-resource level.
403 means the server found something but will not return it
403 Forbidden means the request is understood but access is denied. File permissions, Nginx rules or access restrictions may be responsible.
DNS, the port and TLS are no longer the main suspects.
502 is almost shouting: “look at the application”
location / {
    proxy_pass http://127.0.0.1:3000;
}
With 502 Bad Gateway, Nginx accepts the request normally but does not receive the expected response from the application. The possible causes are now specific: the application is not running, is listening on another port, the process crashed, or the wrong address is configured.
503 — the service is temporarily unavailable
503 Service Unavailable usually means the service cannot handle the request right now: maintenance mode, overload, or a backend problem.
504 — someone is taking too long to answer
504 Gateway Timeout often appears when Nginx passed the request to an application but did not receive a response in time. The backend may exist but respond too slowly — for example, because it is stuck on a database or external API.
500 — the application started, but something went wrong
500 Internal Server Error usually means the request reached the application but an error happened inside it. If the user sees 500 through working HTTPS, there is no reason to begin with DNS and certificates: that part of the chain has already worked.
This is exactly why logs matter
When the interface says only 500, a log can say much more.
database connection refused
permission denied
environment variable not found
address already in use
At this point, the problem stops being a mystery. Logs are not a last resort; they are a normal part of diagnostics.
Nginx has logs too
/var/log/nginx/access.log
/var/log/nginx/error.log
access.log helps determine whether a request arrived and which status code was returned. error.log often explains why a file could not be opened or an upstream service was unavailable.
The most useful check: does the request appear in the logs at all?
If the user opens the site and no new entry appears in access.log, the request probably never reached this Nginx. Go backward: DNS, IP, port, another server, CDN or proxy.
If the entry appears, Nginx received the request. The previous stages can mostly be ruled out.
Do not restart everything at once
restart nginx
restart app
restart database
change DNS
renew certificate
reboot server
The site may start working afterward, but the cause will remain unknown. It is more reliable to change one thing at a time, check the result, then continue.
Four common situations
The site works on the server, but not from outside
If a request to localhost works but a request from another computer does not, the problem looks like a network boundary. The application may listen only on 127.0.0.1, an external port may be blocked by a firewall, or the request may not reach the machine.
It worked yesterday, but not today
A useful question is: what changed? Did the certificate expire? Did the server reboot? Did the application fail to start automatically? Is the disk full? Was a package updated? Did an external service fail?
Even if nobody “touched anything,” systems change over time: deadlines expire, disks fill, processes crash.
Check the disk
When disk space runs out, an application may stop writing logs, creating temporary files, using the database, updating or restarting.
No space left on deviceCheck application processes and ports
If Nginx proxies a request to an application, make sure the process actually exists and listens on the expected port. For example, Nginx sends traffic to 127.0.0.1:3000, but after an update the application starts on 127.0.0.1:3001.
Both systems are healthy. They are simply talking through different doors.
Do not forget the database and external APIs
The chain may continue: browser → Nginx → application → database → external API. If the database is unavailable or a third-party service returns an error, all of the site’s outward-facing infrastructure can be correct while a feature still fails.
“The site will not open” and “the site works incorrectly” are different problems
If the browser cannot establish a connection at all, inspect the early layers: DNS → network → port → TLS. If the HTML has already loaded but data is missing, you are much farther down the chain: Nginx → application → API → database.
You can turn diagnostics into one ladder
Do not go backward without a reason
You checked DNS and it returns the correct IP. Do not change it again because of a 502. The certificate is valid — do not reissue it because of an application error. Nginx chose the right block — do not rewrite the virtual host because the database is broken.
Each confirmed layer should be treated as temporarily innocent.
After the fix, check the chain again
Does the domain open? Does HTTPS work? Is there a certificate warning? Does the home page load? Does the API work? Is there a new error in the logs?
This confirms that you fixed the cause rather than merely changing the symptom.
Then ask: why did it happen?
There are two levels of repair. The first is to restore the site. The second is to make sure the problem does not happen again.
If the application had to be started manually, why did it not start after a reboot? If the certificate was renewed by hand, why did automatic renewal fail? If the disk was cleaned, why did nobody notice it was filling up?
Monitoring is diagnostics in advance
The ideal situation is to learn about a problem before the user does. That means watching site availability, HTTP status codes, certificate expiry, disk space, application state and error growth.
Then, instead of “the site has been down for two hours,” you can get “the application stopped responding 40 seconds ago.”
The most useful habit for an administrator
It is not memorizing every command. It is not remembering every Nginx parameter. The most useful habit is simpler: split the system into layers.
Not “the internet is broken,” but “DNS is correct → 443 responds → TLS works → Nginx returns 502 → the application on port 3000 is not running.”
The second sentence no longer sounds frightening. It is an ordinary task.
The whole website stops looking like magic
The domain gives a human-readable name. DNS turns the name into an IP. The network carries the request to the server. The port defines the entry point. TLS creates a protected connection. The certificate helps verify the domain. Nginx chooses the right site and route. A file or application creates the response. The browser shows the result.